Latest
5 min read
Multi-agent systems: when it helps
Most multi-agent demos don't beat one well-prompted agent. When coordination is worth the added latency and failure surface, and when it's overhead.
Notes on AI engineering — RAG, agents, evaluation, and the production-grade infrastructure around them.
Most multi-agent demos don't beat one well-prompted agent. When coordination is worth the added latency and failure surface, and when it's overhead.
Chunk-level allowlisting, output filtering, privilege separation for agents. Concrete defenses against retrieved-content injection, not the theory.
0.87 makes strict TypeScript types the default. But the headline feature is not what decides the upgrade — the removals and the toolchain bumps are.
Authentication is a fact you establish once. Authorization is a decision you make on every request — and that gap is where most access-control bugs live.
An eval set built in March measures something else by June. The three things that drift — corpus, query distribution, judge — and how to catch each one.
A prompt is an interface. Treat it like code — versioned, eval-gated, with a rollback path — not a string anyone can edit live in a CMS with no review.
Most RAG evaluation advice stops at build a labelled set and use LLM-as-judge. This is the workflow: sampling real queries, and calibrating the judge.
Reranking top-50 down to top-5 routinely beats raw retrieval by 10+ recall points. What a cross-encoder does differently, and the 50 lines that call one.
Re-embedding the corpus is the easy part. What actually breaks when you change embedding models in production, and the evals I run on either side of the swap.
Most problems people reach for an agent to solve are workflow problems with extra steps. A decision framework for telling the two apart before you build.
Vector search ranks by similarity, not permission. Why multi-tenant RAG leaks across tenants by default, and where the authorization check actually has to sit.
Mobile engineers spent a decade learning to ship software they couldn't take back. LLM teams are relearning the same four constraints, usually the hard way.
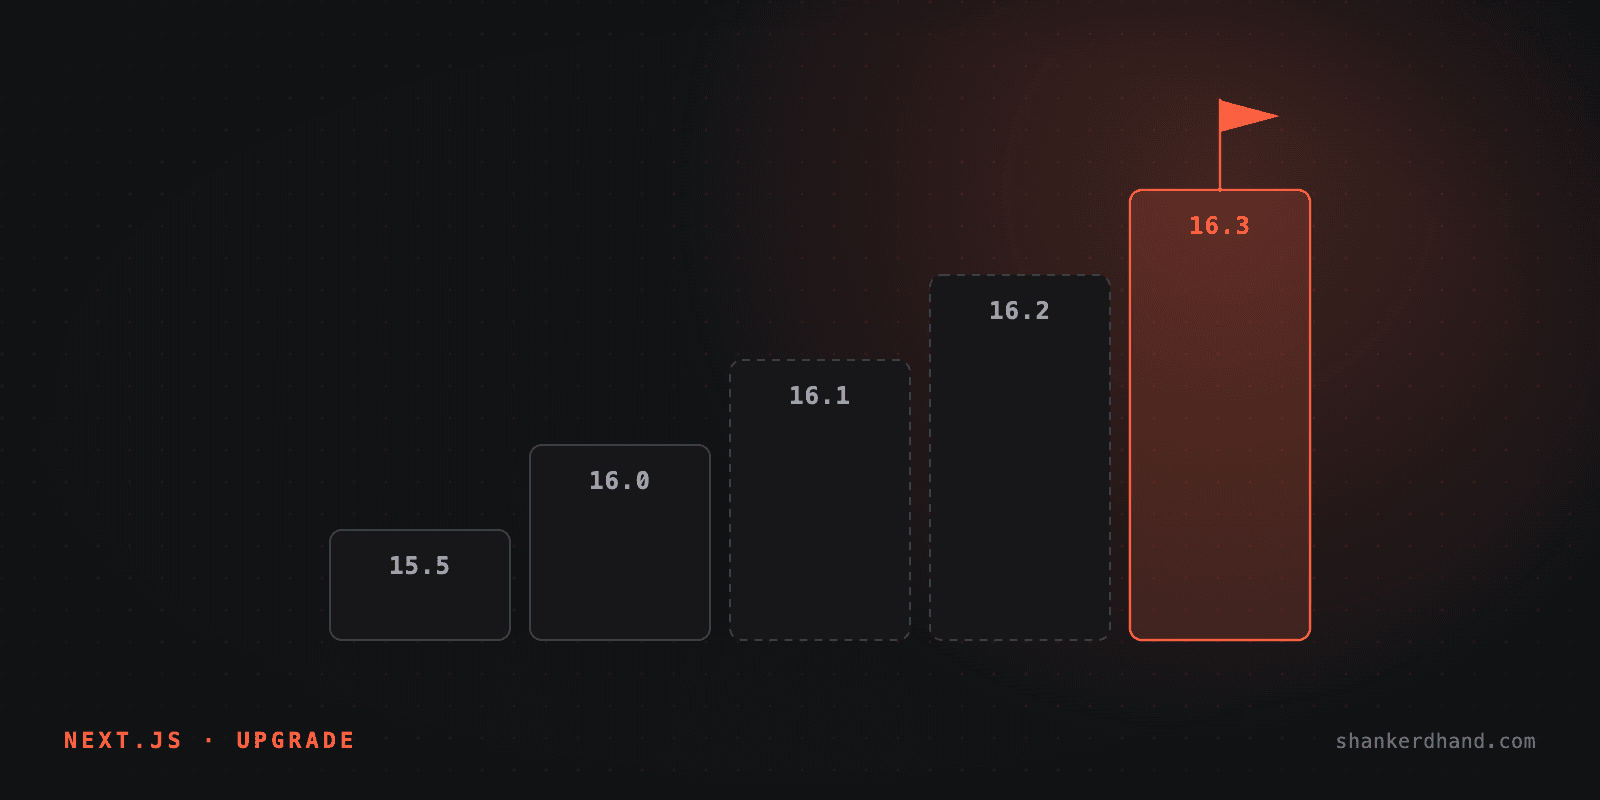
turbopackUseSystemTlsCerts was removed in Next.js 16.2: Turbopack now trusts OS certificates by default. Plus the two 16.3.3 security fixes: patch or migrate?
pgvector for embeddings, LISTEN/NOTIFY for jobs, row-level security for tenant isolation. One database instead of four services — and the signals to split.
Not legal advice — the five-field logging pattern I'd want on any agent that takes real actions, and why a log you cannot replay is only a transcript.
Pick on task shape — latency, accuracy, cost, context length — not leaderboard rank. A model that wins on average isn't better on every one of your queries.
Prompt caching, model routing, and compression actually move an LLM bill. What each one does, what it doesn't, and the dashboard to build before you need it.
Dense embeddings and BM25 fail on different queries, and real corpora have both. Reciprocal rank fusion in pgvector, and when pure vector search still wins.
Tool-use loops with no exit, hallucinated arguments, state leakage, over-confident planning, retry storms — five failures I keep seeing, and what stops each.
Cardinality, sampling, replay and PII handling for an LLM system — what to log unconditionally, what to sample, and what to keep out of your logs entirely.
The 2026-07-28 MCP spec ships a stateless core, deprecates Roots, Sampling and Logging, and assumes OAuth 2.0. What breaks, what to migrate, and when.
Fixed-size, semantic, and structure-aware chunking all look fine in a demo. Here's how each one actually fails once real documents hit your production pipeline.
A practical comparison of pgvector, Pinecone, Qdrant, and Weaviate — real cost and latency numbers from production, and why pgvector is usually enough to start.
What separates a working RAG demo from a production RAG system isn't the retrieval — it's the evaluation, observability, and failure-mode handling around it.
Why I'm writing about AI engineering: notes on shipping RAG systems, LLM agents, and unglamorous full-stack work that decides whether it survives production.